NLPML· Mar 2026
University FAQ Chatbot
An NLP chatbot that answers student questions instantly — and says "I don't know" instead of guessing.
- confidence cutoff before it falls back
- 0.40
- Built with
- PythonNLTKscikit-learnpandasStreamlit
Problem
Students ask the same questions over and over. Staff spend time repeating answers that already exist in an FAQ — and a chatbot that confidently gives the wrong answer is worse than none at all.
Approach
- Preprocessing pipeline with NLTK: lowercase → domain synonym map (
enroll → apply,tuition → fees,dorm → housing) → tokenize → remove stopwords → lemmatize. - Retrieval with a scikit-learn
TfidfVectorizerfitted once at startup, then cosine similarity to find the closest FAQ. - Confidence threshold (0.40): below it, the bot gives a safe fallback instead of a wrong answer.
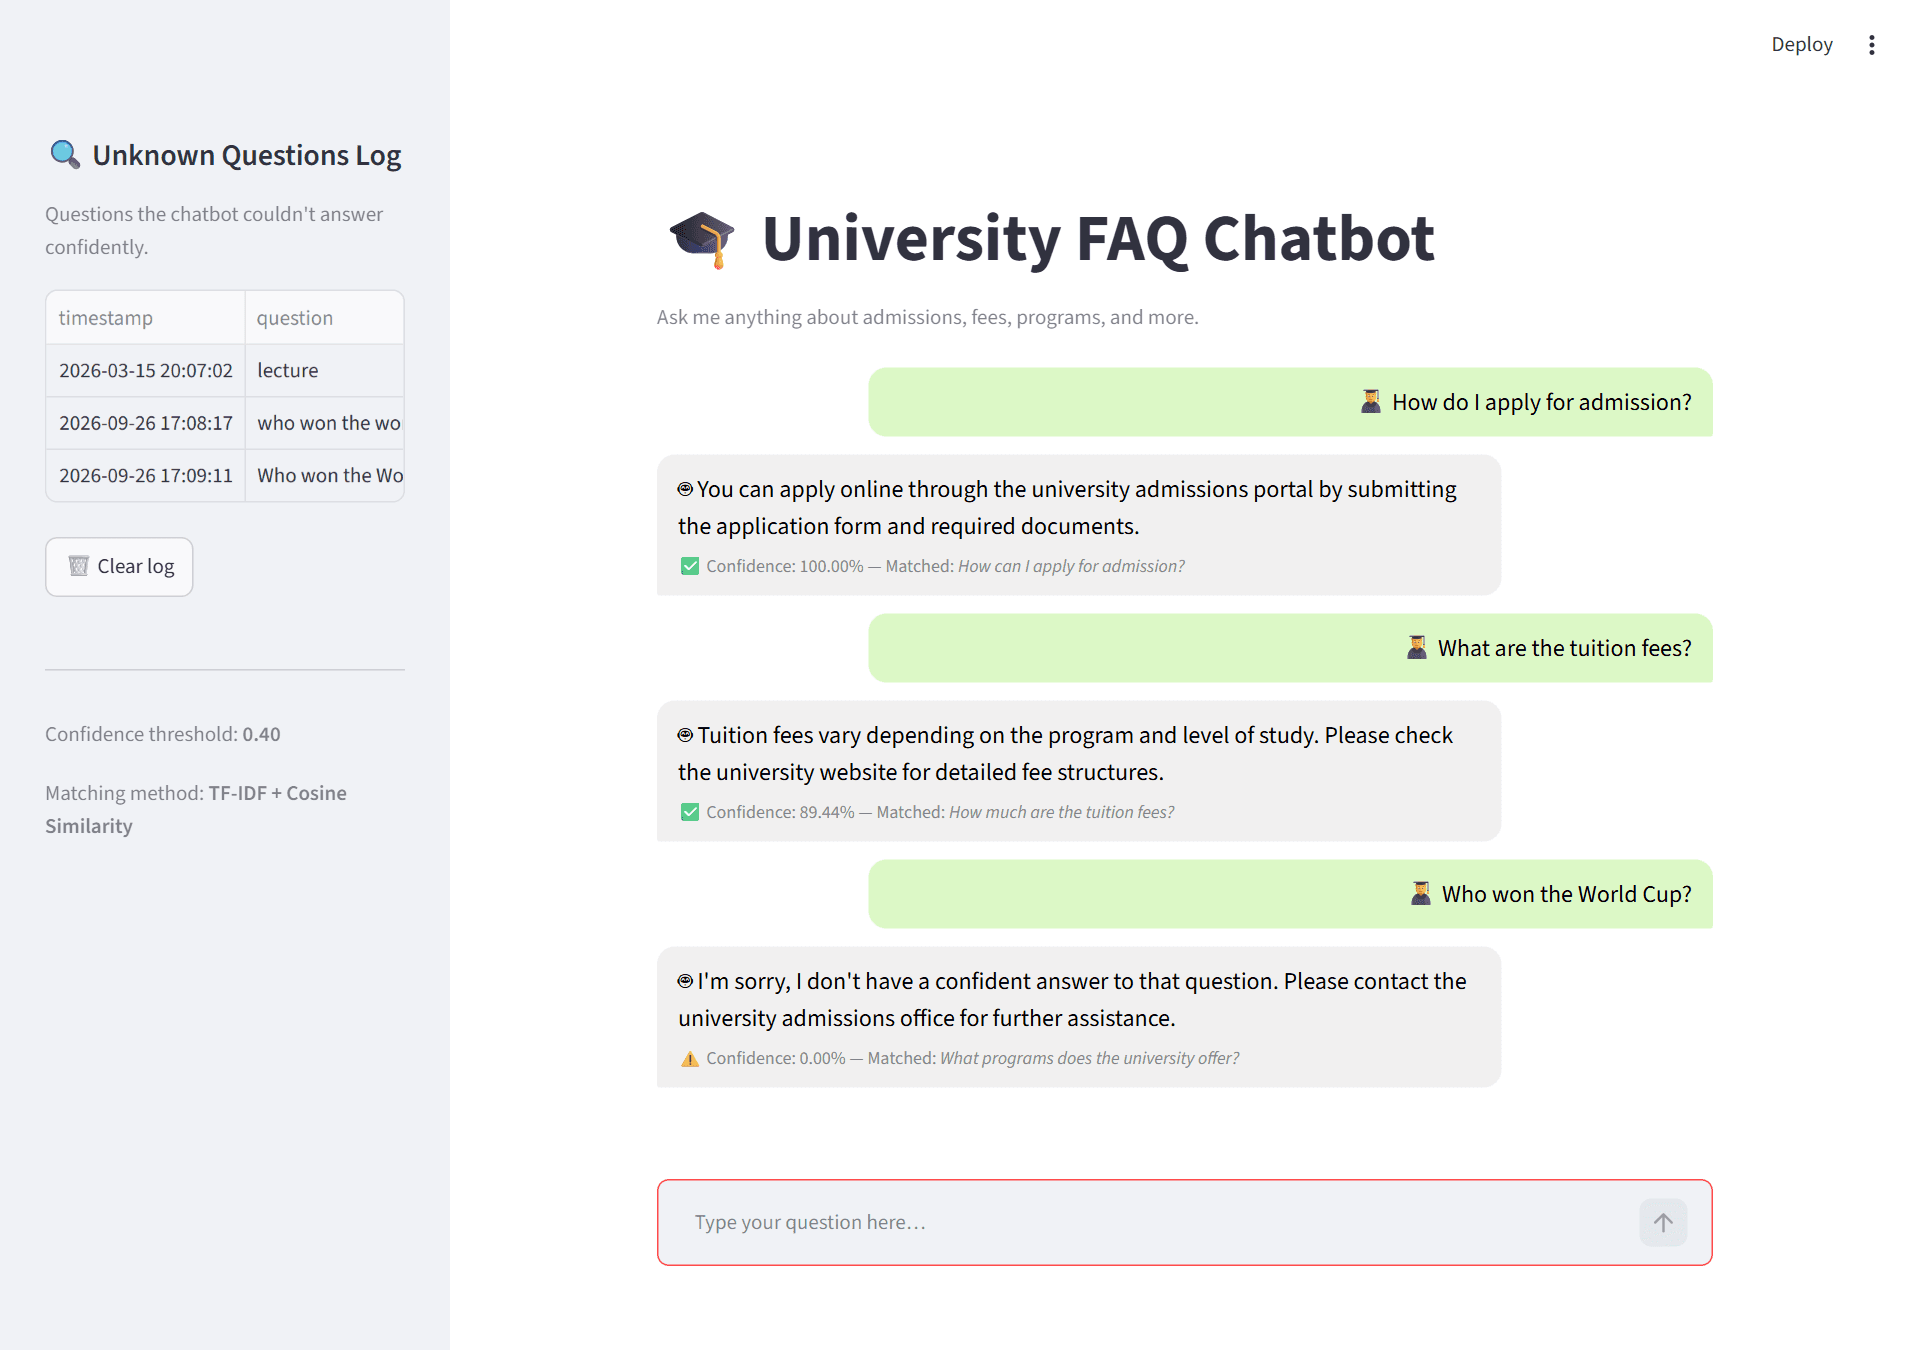
- Gap logging: low-confidence questions are written to a CSV and shown live in the sidebar, so admins know which FAQs to add next.
- Two interfaces — a Streamlit chat app and a CLI — sharing one engine module.
Results
- Paraphrased questions like "How do I enroll?" land on the right FAQ without training a model or calling an API.
- In the demo, "How do I apply for admission?" matches at 100% confidence and "What are the tuition fees?" at 89.44%. An off-topic question ("Who won the World Cup?") scores 0% and gets the fallback — and is logged.
- The knowledge base is a CSV: editing
data/faqs.csvchanges the bot's answers with no code changes.
What I learned
- Classic NLP still goes a long way — TF-IDF + cosine similarity handles paraphrases well.
- Preprocessing matters as much as the model.
- A confidence threshold makes a bot trustworthy: saying "I don't know" and logging the gap beats a confident wrong answer.
- Splitting preprocessing, vectorization, similarity and UI into modules let me add the CLI without touching the engine.
Next steps
- Swap TF-IDF for sentence embeddings to catch synonyms automatically.
- Admin page to add FAQs from logged unknown questions.
- Unit tests for the preprocessing pipeline.